Data Ingestion & Pipeline Engineering
Ingest batch, API, database, file, event, and streaming sources through monitored pipelines designed for scale, recoverability, and predictable processing.
Build reliable, governed data pipelines that turn operational information into trusted inputs for analytics, automation, enterprise reporting, and AI.
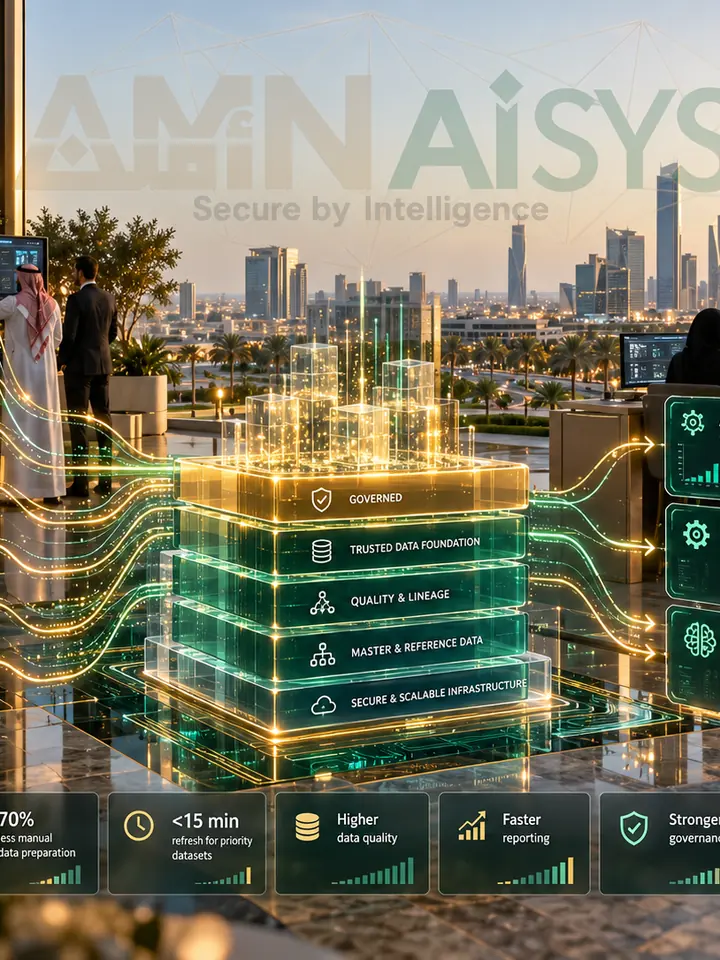
AMNAISYS engineers data movement, transformation, quality, lineage, and serving layers so teams can work from consistent information instead of reconciling disconnected extracts.
Ingest batch, API, database, file, event, and streaming sources through monitored pipelines designed for scale, recoverability, and predictable processing.
Clean, standardize, enrich, and model raw source data into trusted structures for reporting, operational applications, automation, and analytical workloads.
Apply validation rules, schema checks, completeness tests, duplicate detection, and exception routing before unreliable data reaches downstream consumers.
Document where data originates, how it changes, who owns it, and which systems consume it so important datasets remain understandable and auditable.
Prepare curated datasets, marts, APIs, and query layers for dashboards, planning, performance analysis, and operational decision support.
Structure, segment, label, secure, and index enterprise information for retrieval-augmented generation, knowledge assistants, automation, and model evaluation.
Data pipelines are engineered with validation, lineage, ownership, security, and monitoring so analytics and AI are built on information the organization can explain and trust.
Identify the decisions, reporting, automation and AI use cases the data platform must support.
Define source ownership, data models, quality rules, lineage, permissions and retention requirements.
Engineer batch and real-time ingestion, transformation, validation and serving layers across enterprise data sources.
Track freshness, completeness, failures and downstream consumption so trusted data remains reliable in production.
Give teams consistent definitions, quality checks, and governed datasets so reports are not rebuilt from conflicting spreadsheets and extracts.
Automate ingestion and transformation so priority information reaches dashboards, workflows, and applications with less delay.
Replace repeated download, cleanup, merge, and reconciliation tasks with monitored data pipelines and reusable transformations.
Create secure, structured, traceable datasets and knowledge sources that AI applications can retrieve, evaluate, and use reliably.
Focused solution patterns show how the capability can be applied to real operational priorities.
Convert incoming documents into validated structured data, route exceptions for review, and deliver approved records to downstream systems.
ExploreUnify priority operational sources into governed datasets and serving layers for dashboards, performance analysis, and management reporting.
ExplorePrepare policies, procedures, product information, and internal documents for permission-aware search, RAG, and enterprise AI assistants.
ExploreSERVICE FAQ
Yes. Data engineering often begins by mapping sources, ownership, formats and quality issues, then building governed pipelines and models that create a more reliable information layer.
Yes. The architecture can combine scheduled batch processing, event streams and near-real-time ingestion depending on the business use case and source-system capabilities.
Quality rules can check completeness, validity, freshness and consistency, with lineage and ownership defined so issues can be traced to their source.
Yes. Pipelines, access controls, metadata and serving layers can be designed to support analytics, automation, retrieval systems and enterprise AI workloads.
Define the source systems, quality rules, governance model, latency requirements, and target consumers with AMNAISYS.